sūveryn › Litigation lawyers
Your data. Your premises. Your AI.
Litigation runs on documents you can’t share: privileged advice, witness statements, expert reports, strategy notes. Sūveryn gives your litigation team AI that reads, summarises and searches them on a server you own, in your own office or server room. Nothing goes to a cloud provider, a model vendor or an AI start-up in between.

Most cloud-based legal AI tools upload your documents to someone else’s servers. With sūveryn, the model, the documents and every question your team asks stay on hardware you control. It works fully offline and even air-gapped, so a dossier under seal or a sensitive investigation never touches the internet.
Many “legal AI” products are wrappers: a branded interface that sends your prompts and files to another company’s model, often in another jurisdiction. Their answer to confidentiality is a contract: an EU region, a no-training clause, a retention limit. As the CCBE puts it, “the less we control the stack, the more we must ensure the control by contractual obligations to the provider and rely on promises from a vendor.” Sūveryn takes the other route. Nothing leaves your premises, so there is nothing to negotiate, and you can prove it: switch it to air-gapped mode and it keeps working.
| A typical AI wrapper | Sūveryn | |
|---|---|---|
| Where the model runs | On the model provider’s servers | On your server, on your premises |
| Who receives your documents | The tool vendor and the model provider | No one outside the firm |
| What protects your data | Contract clauses: region, retention, no training | Architecture: nothing leaves, even air-gapped |
| Can you check what it does | Closed code | Open-source code and published limitations |
| Works without an internet connection | No | Yes |
| If the vendor changes terms or stops | The service changes or stops | Code (AGPL) and models (Apache 2.0) stay with you |
| Answers checked against the sources | Depends on the product | Each citation checked against its passage; sums calculated by the server |
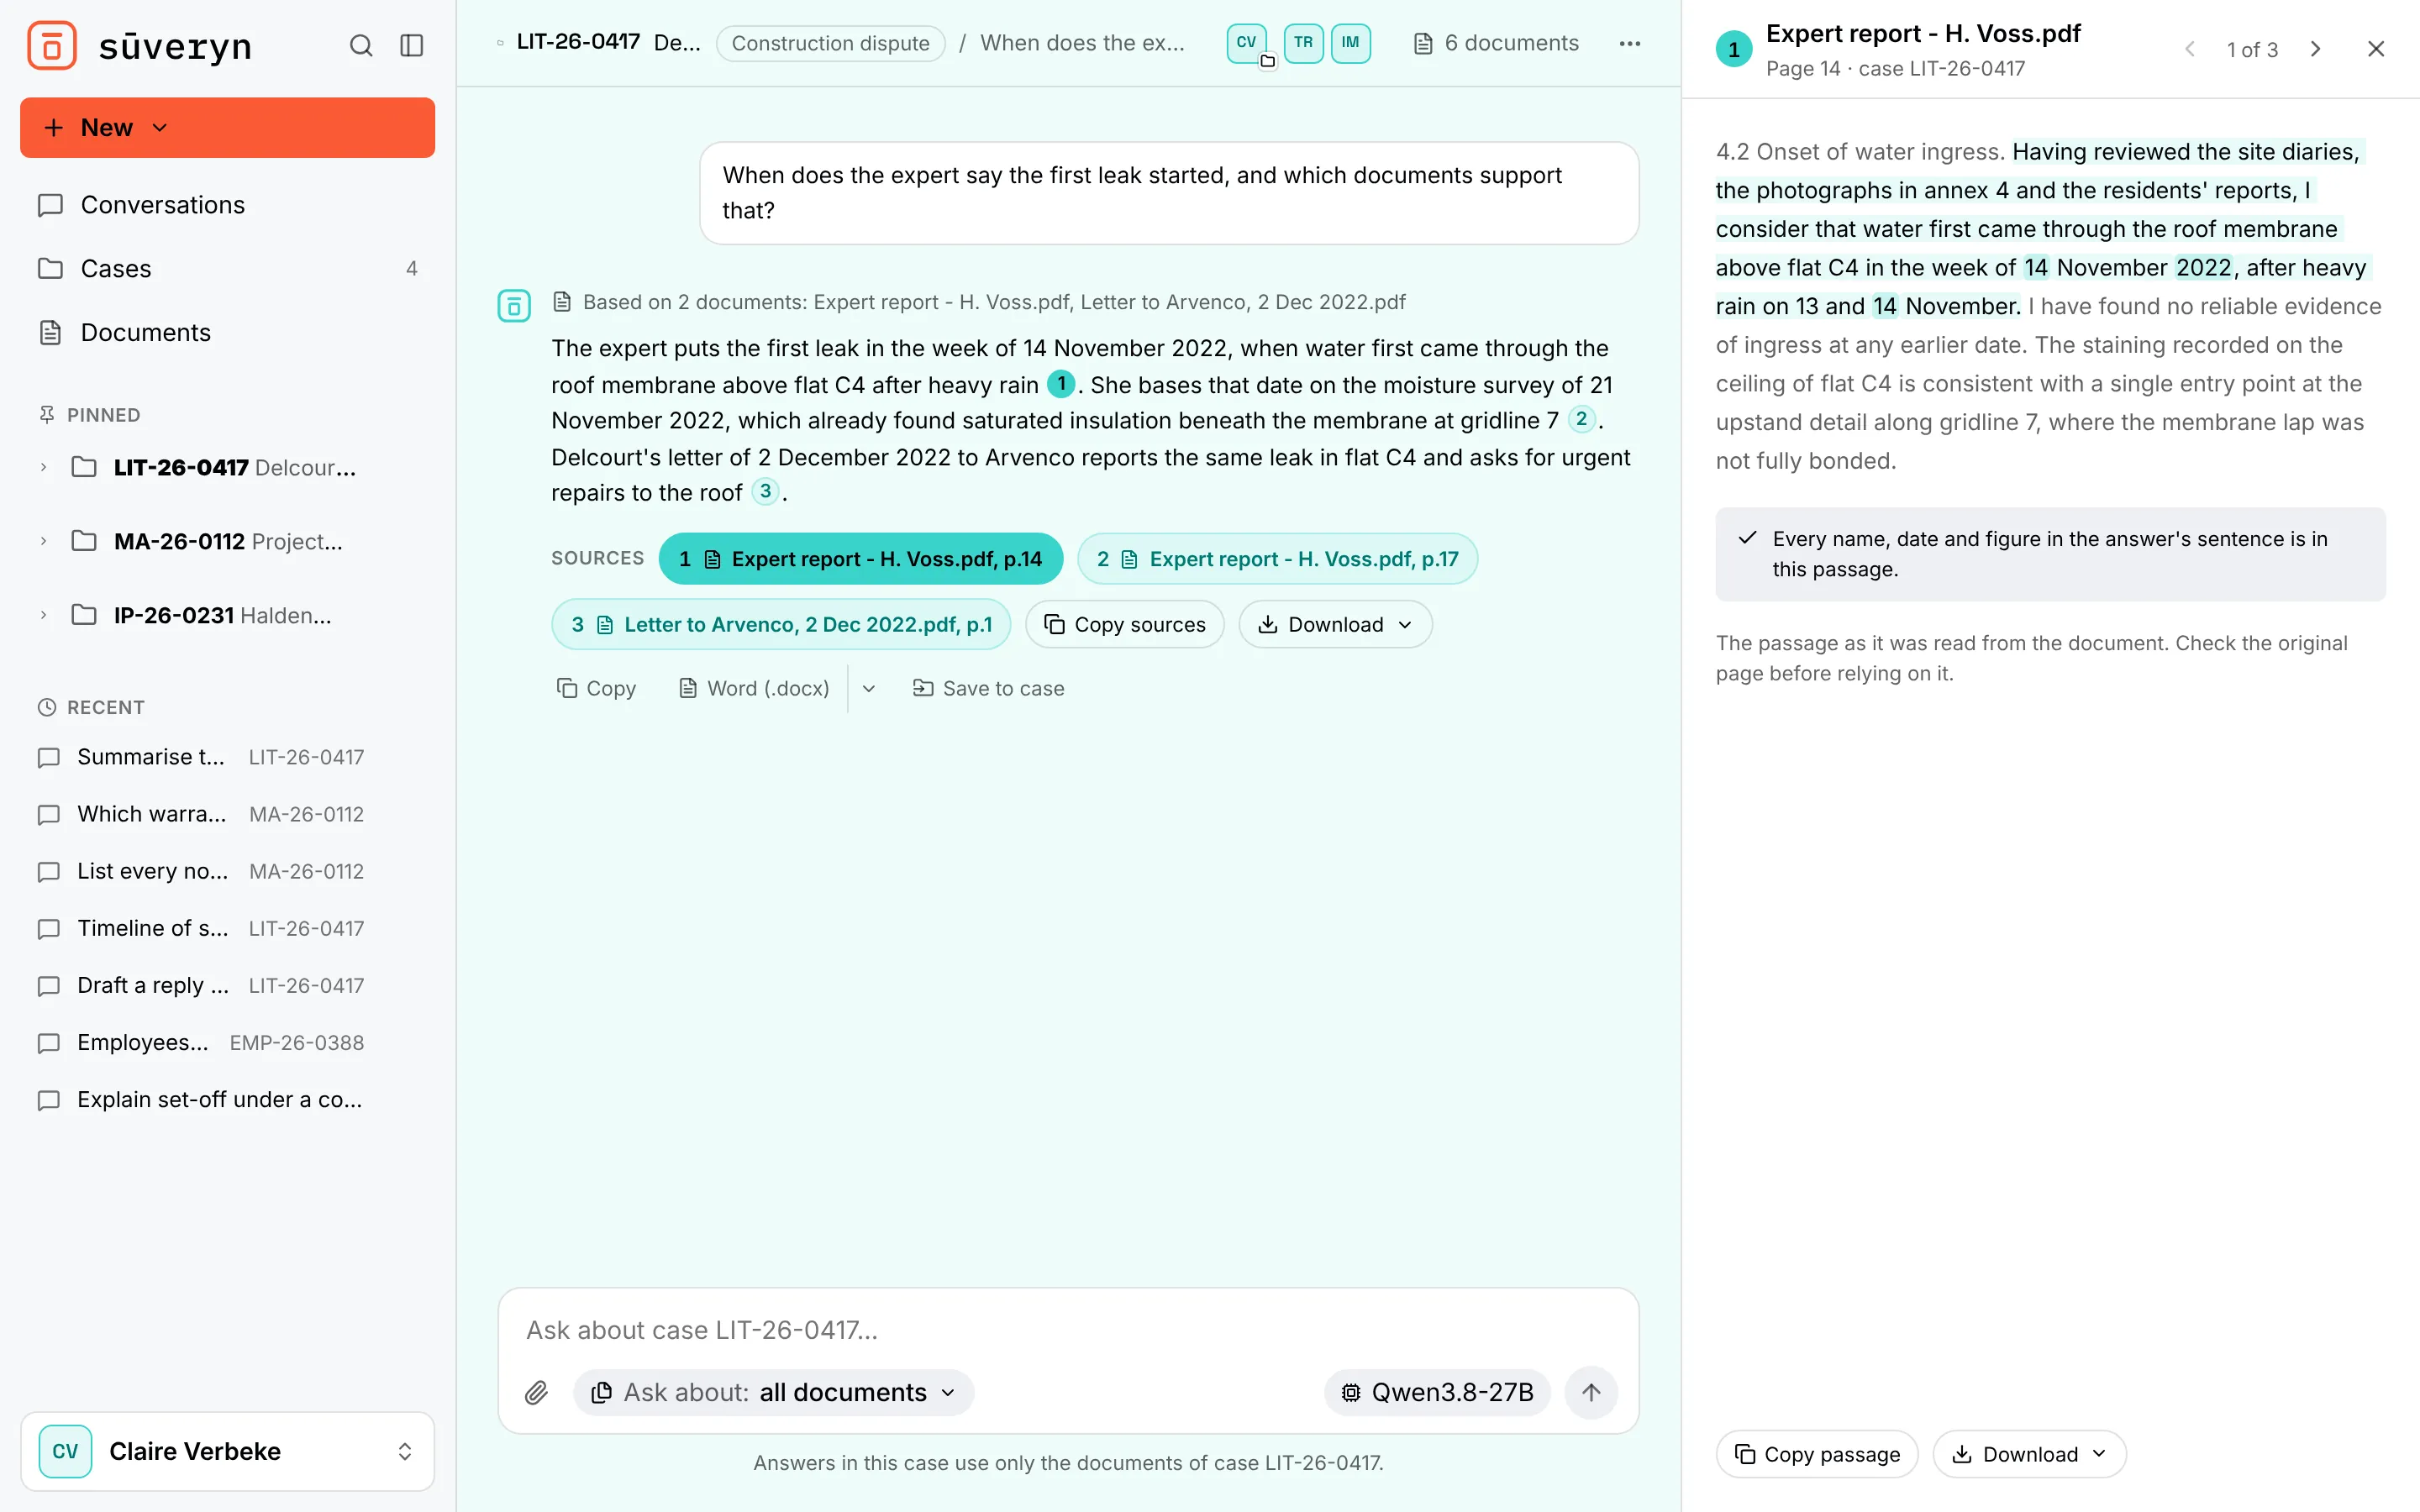
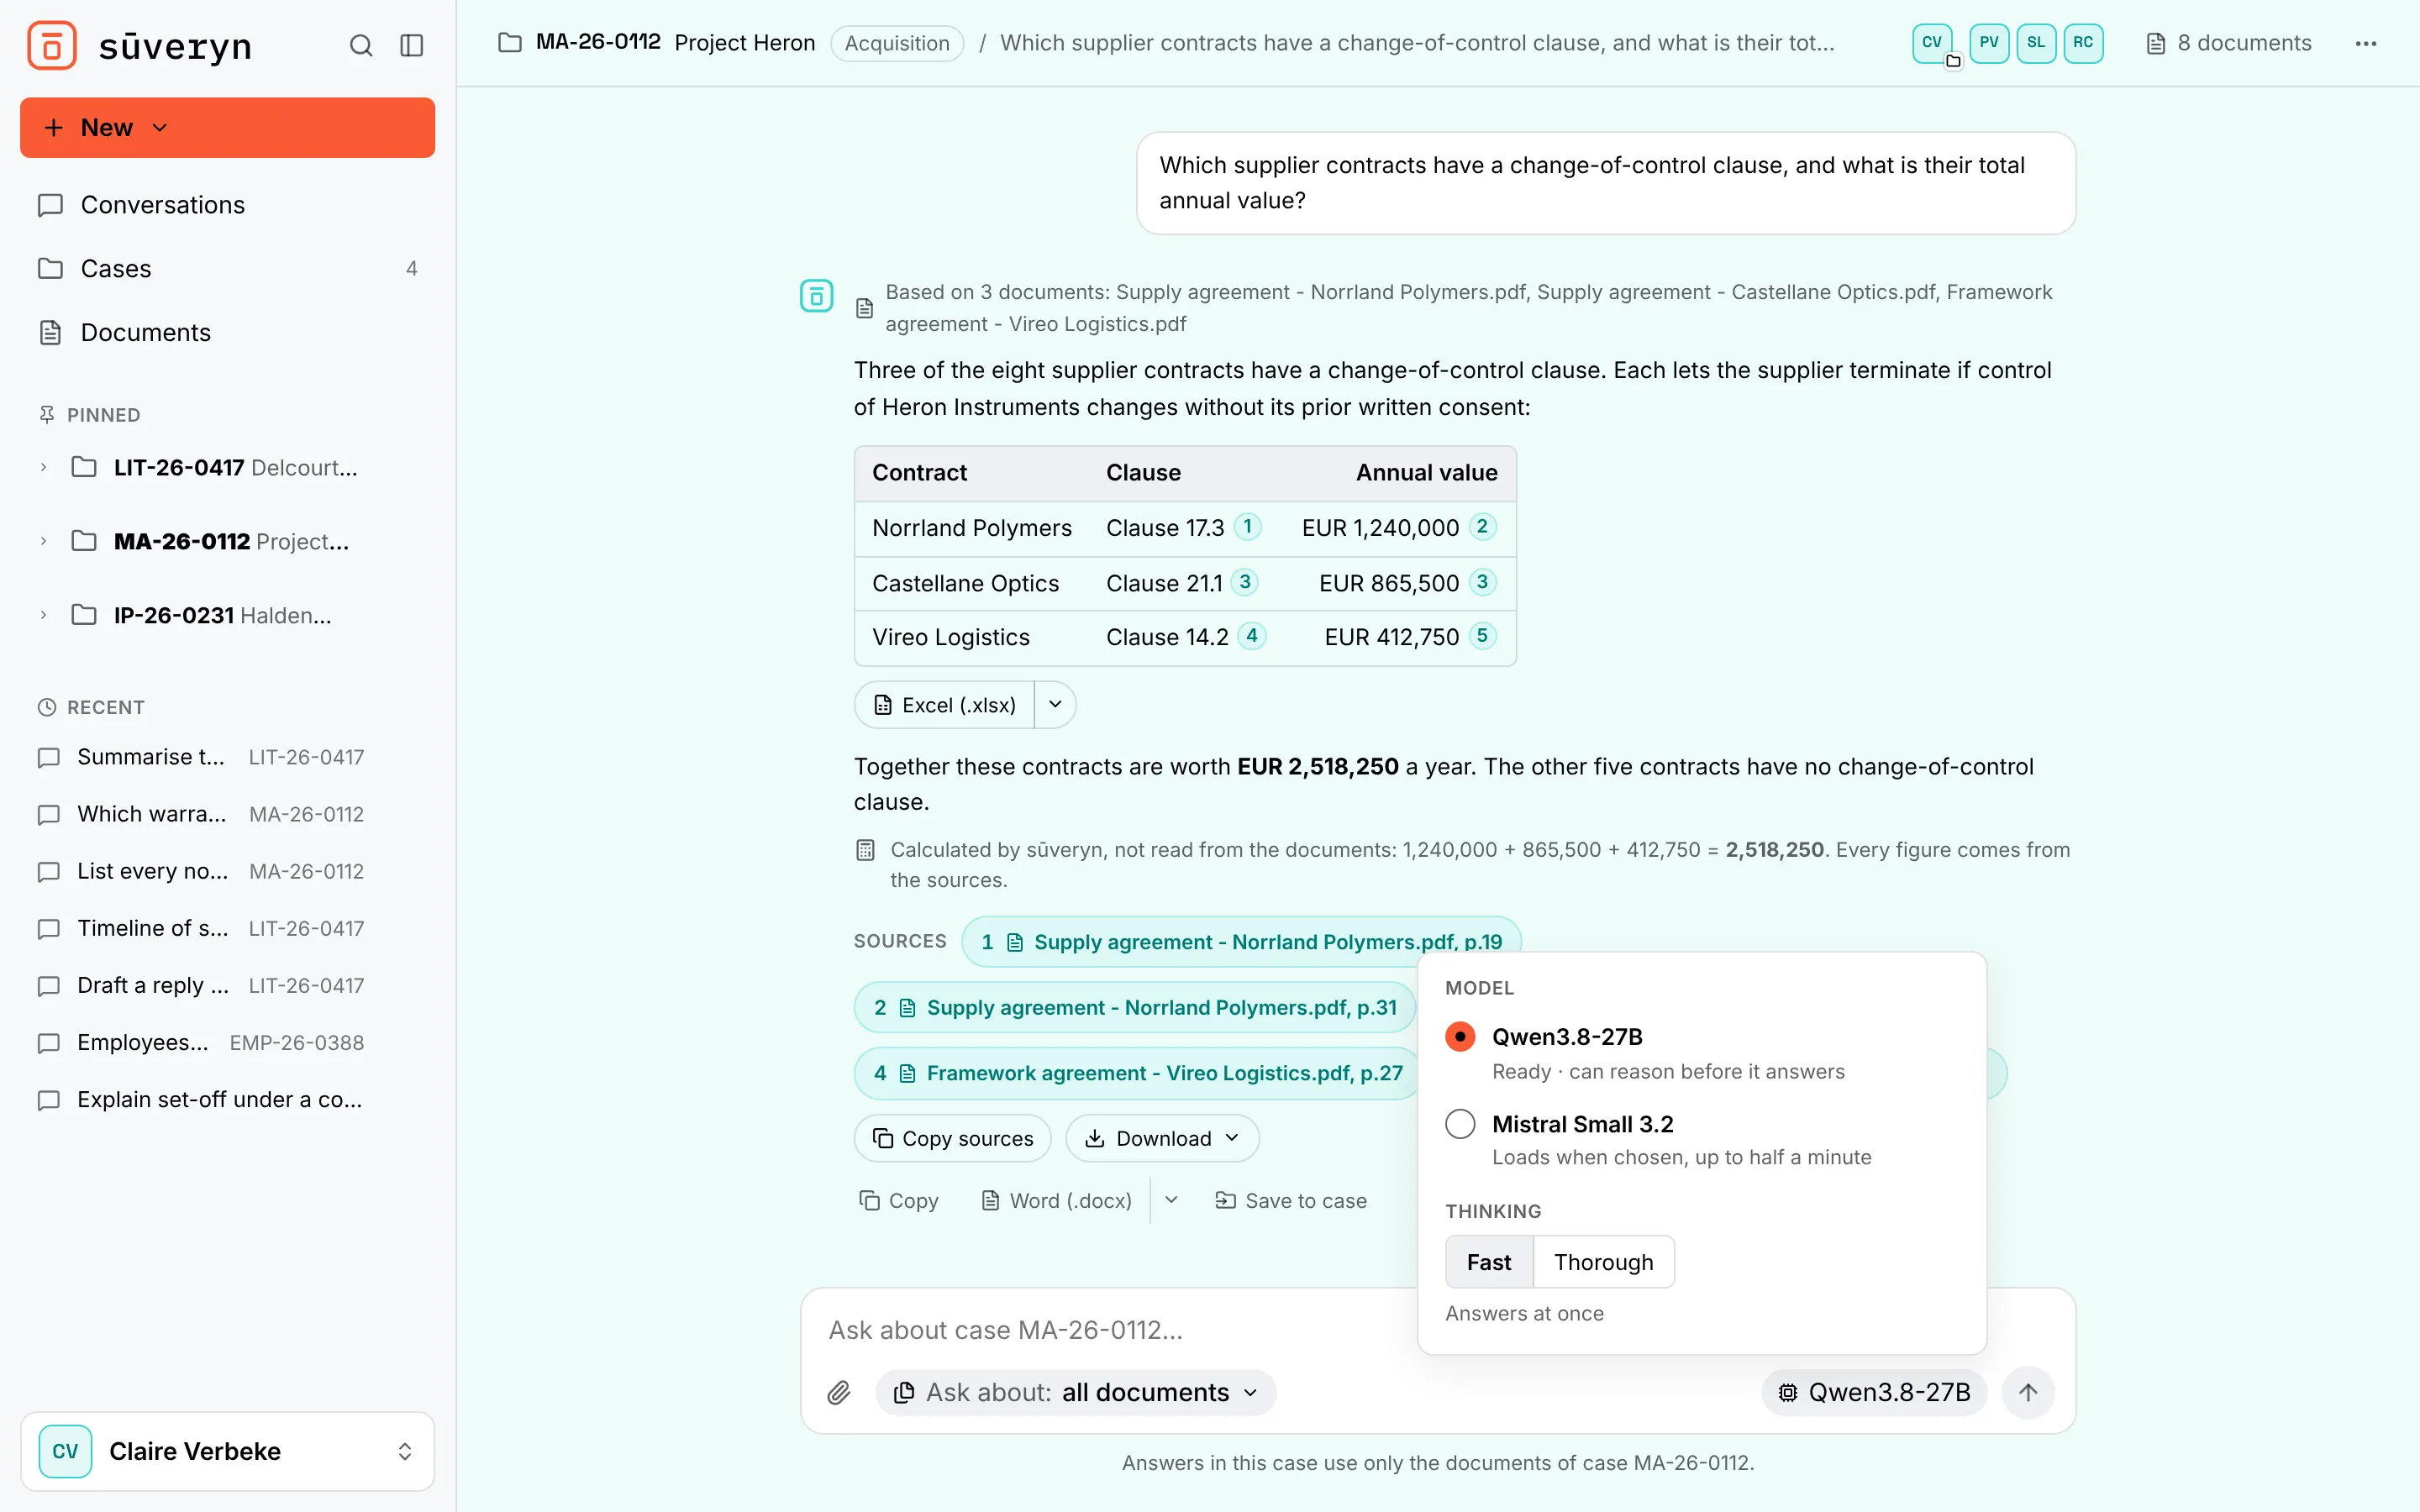
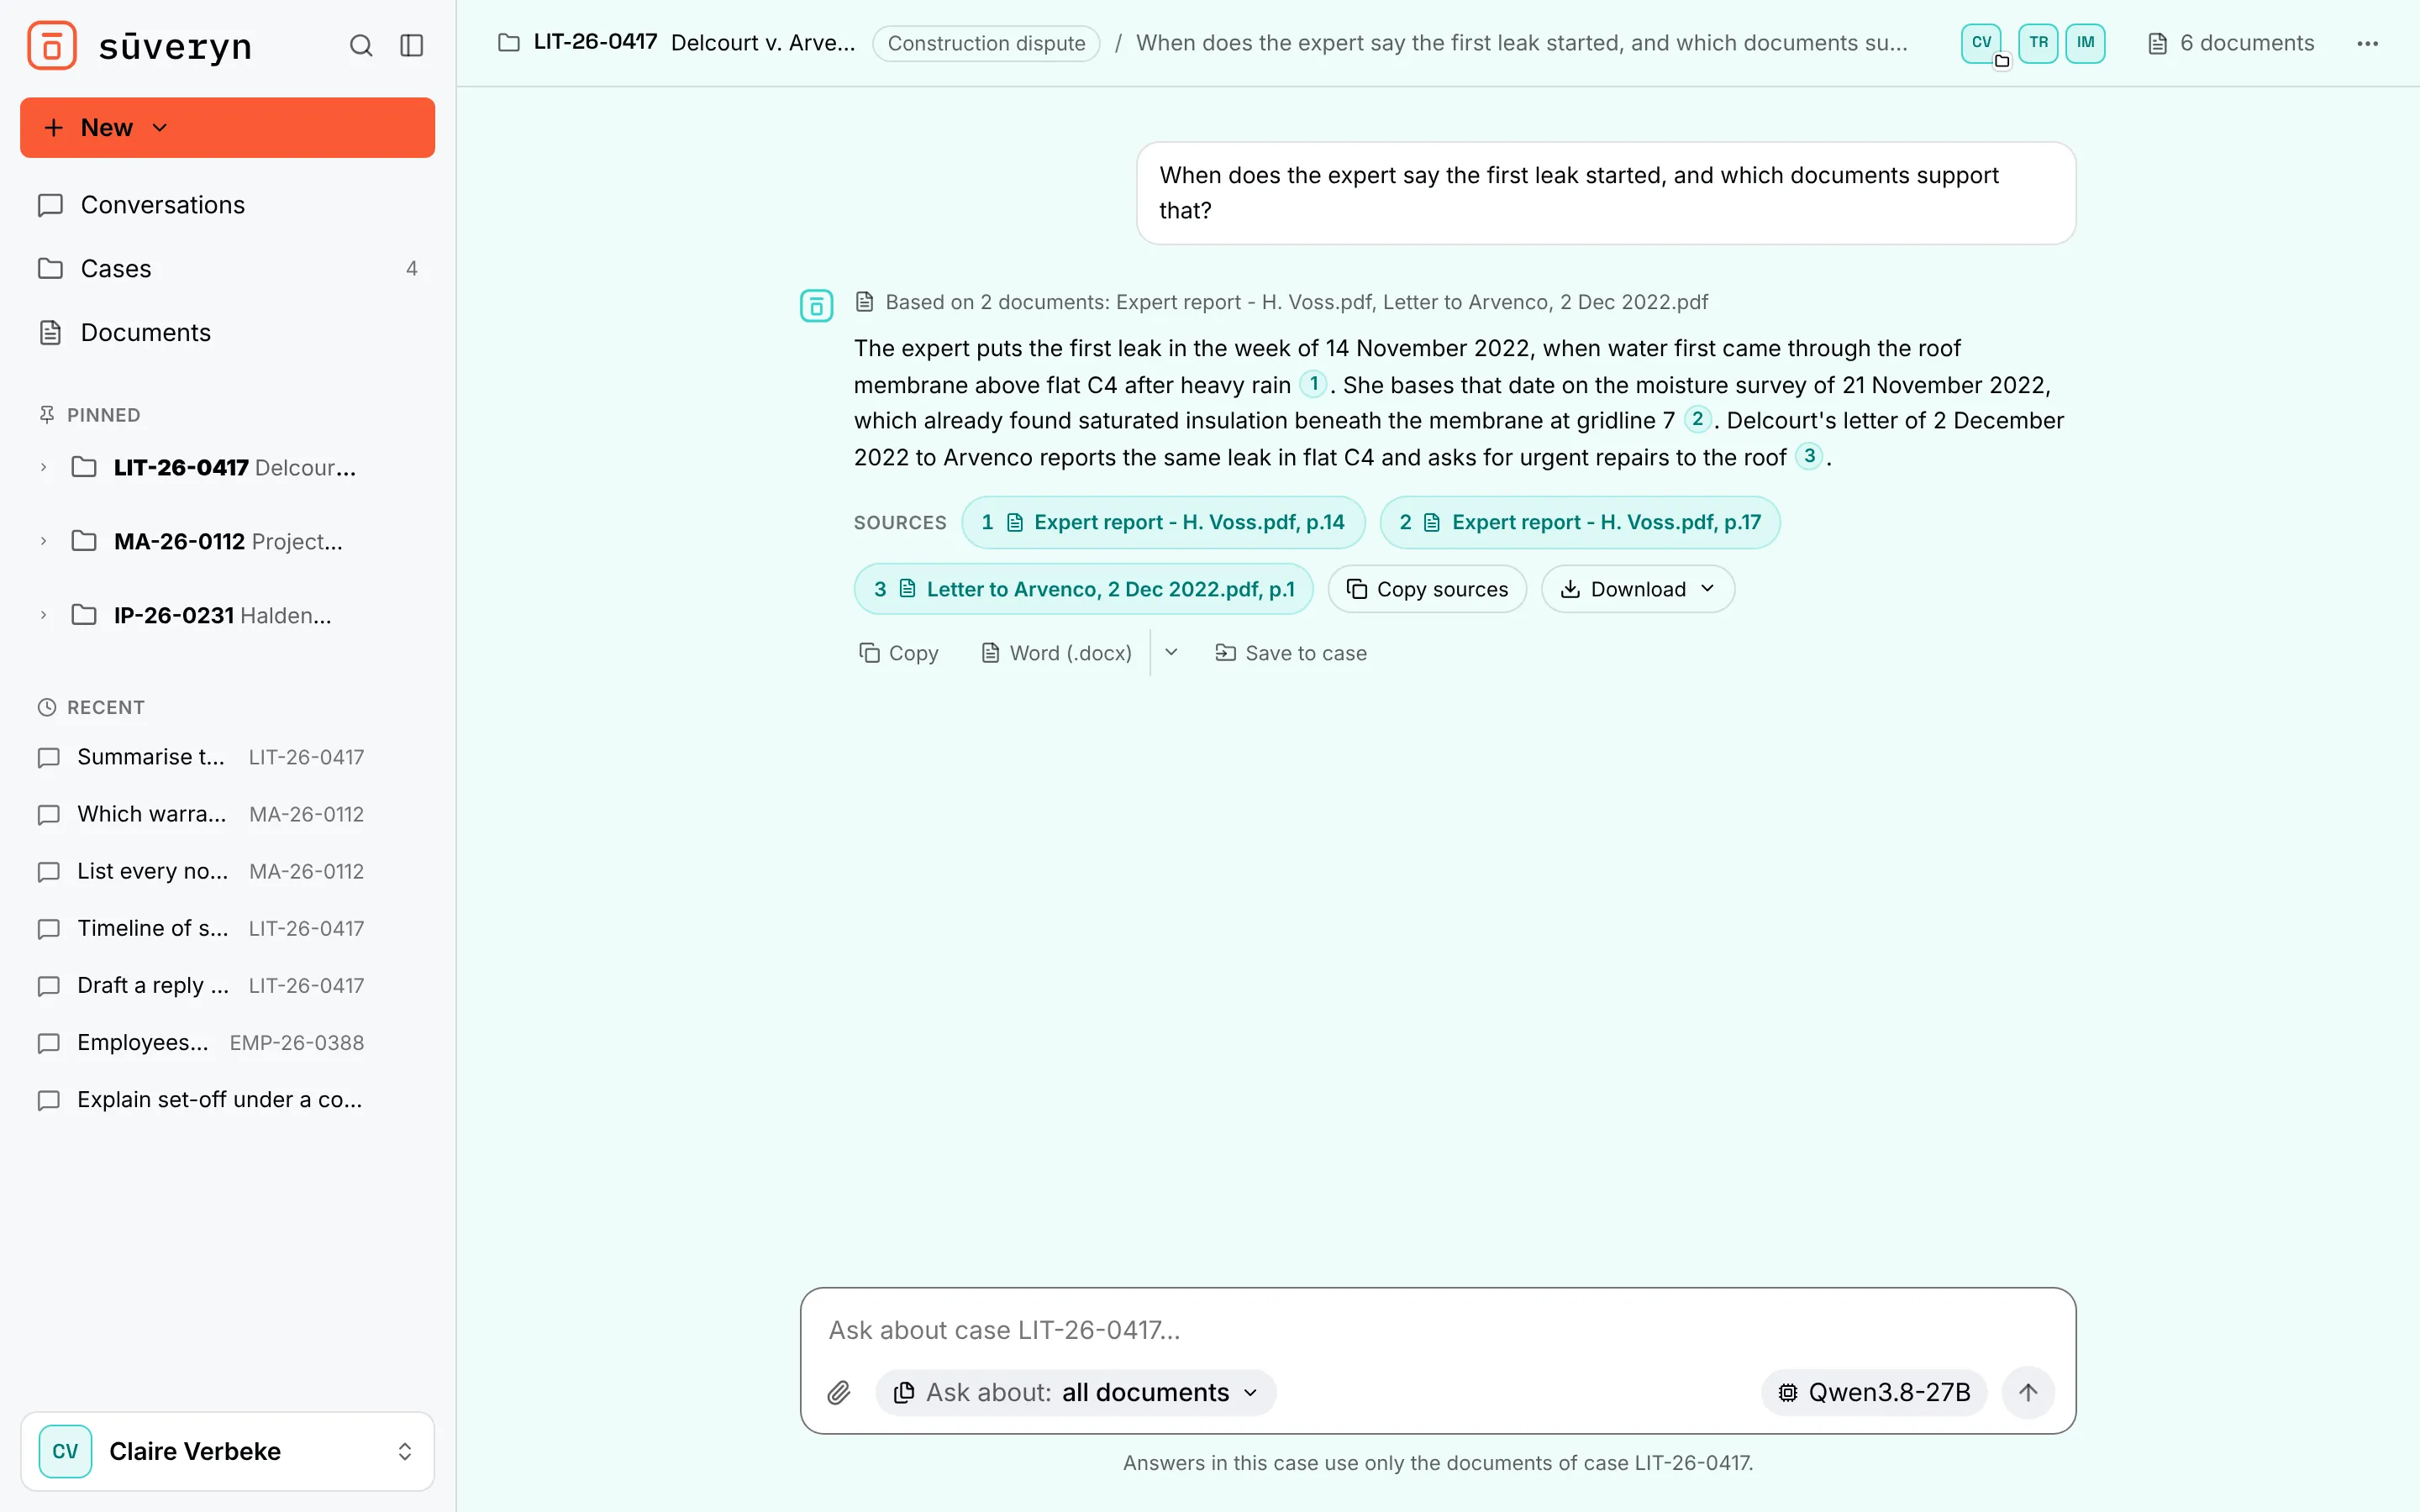
A lawyer can’t use an answer they can’t trace. Every sūveryn answer cites the passages it rests on, with the page, and opens each one with the sentence marked. Each citation is checked against its own passage: a figure, date or name that isn’t there is flagged. Sums are calculated by the server, not by the model. The bars expect lawyers to verify AI output before relying on it; a page citation turns that from an afternoon’s work into a minute’s. And text inside a document is never treated as an instruction, so a planted line in a document from the other side can’t steer the answer.

Europe’s bars point the same way. The CCBE’s technical guide on the use of AI tools and models by lawyers (27 March 2026) calls on-premise deployment “the most secure option regarding the respect for confidentiality”: the data “remains within the control of the lawyer. There is no transfer of data to a third person.” With a cloud service, it warns, “the data leaves user’s environment which, in case of lawyers, can raise confidentiality issues.” The professional duties behind this are in its guide on the use of generative AI by lawyers (2 October 2025). With sūveryn, confidential data stays confined to the firm: on your own premises, under your own access controls, with no outside provider that receives or keeps it.
Clients, insurers and the bar ask more and more how a firm uses AI and where client data goes. With sūveryn the answer is one sentence: it stays on our own server, in our own office, and no outside company sees it. You decide who uses it and on which matters, and you start with a pilot on closed files before anyone relies on it.
Sūveryn ships with two open-weight models, Qwen3.8-27B and Mistral Small 3.2, and your people choose the model per conversation. No model vendor sees your work. It runs on one server with a 24 GB NVIDIA GPU (RTX 4090 class).

Hosting it with your IT provider instead of in your own office needs a data-centre GPU; contact us before planning that.
The code behind sūveryn is open source, so anyone can inspect it: your IT team, an outside security firm, a sceptical partner. That is the point. A tool that holds privileged files shouldn’t ask for blind trust. The code is public; your data never is. Read the Sūveryn Manifesto for why we build this way.
Public AI services process your prompts on the provider’s servers, and terms on retention and training vary. For privileged material, most bars advise against it. Sūveryn keeps everything on your own hardware.
No. It runs fully offline and supports air-gapped networks, and new models arrive as signed bundles you can install without a connection.
Only on the hardware you choose: a server in your own office or server room.
Yes. Any matter where documents can’t leave the firm is the use case it is built for.
Not at everything: the largest cloud models are stronger at open-ended reasoning. For questions about your own files, what counts is that each answer is grounded in the documents and can be checked. Sūveryn cites the page, checks every citation and flags what it can’t trace. The CCBE’s technical guide makes the same point: smaller models trail the frontier models out of the box, but there may be “a ‘sweet spot’ in which a smaller model performs a given task comparably to the commercial frontier systems”. We tested ours on real Belgian deeds and publish the results, limitations included.
Sūveryn is in development. Join the waitlist to run a pilot on your own case files.
Join the waitlist to run a pilot on a closed matter, on a server in your own office, and judge the answers yourself.
Sūveryn for other practices